
Research, experiments, and implementation notes filed under gpu-management.
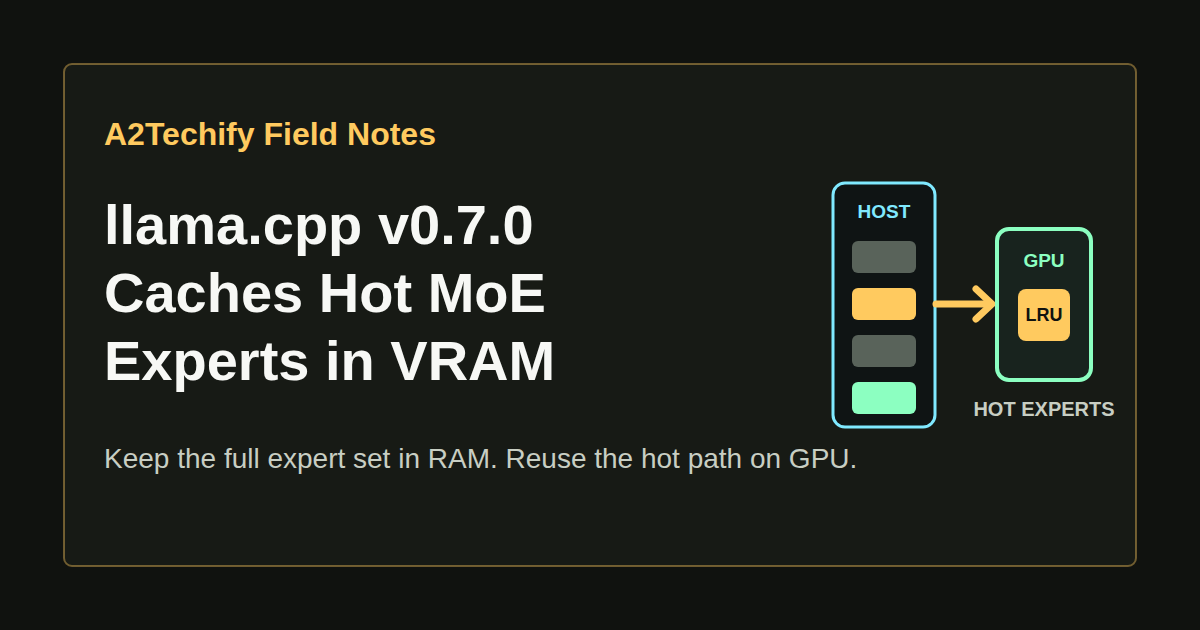
llama.cpp v0.7.0 Adds a GPU Cache for CPU-Offloaded MoE Experts
llama.cpp v0.7.0 can cache frequently used MoE experts on the GPU while keeping the full expert set in system memory.
GPU Scheduling Is Becoming AI Infrastructure Work
A practical look at why GPU allocation order matters for AI teams running mixed training, inference, quantization, and batch workloads.