
Research, experiments, and implementation notes filed under quantization.
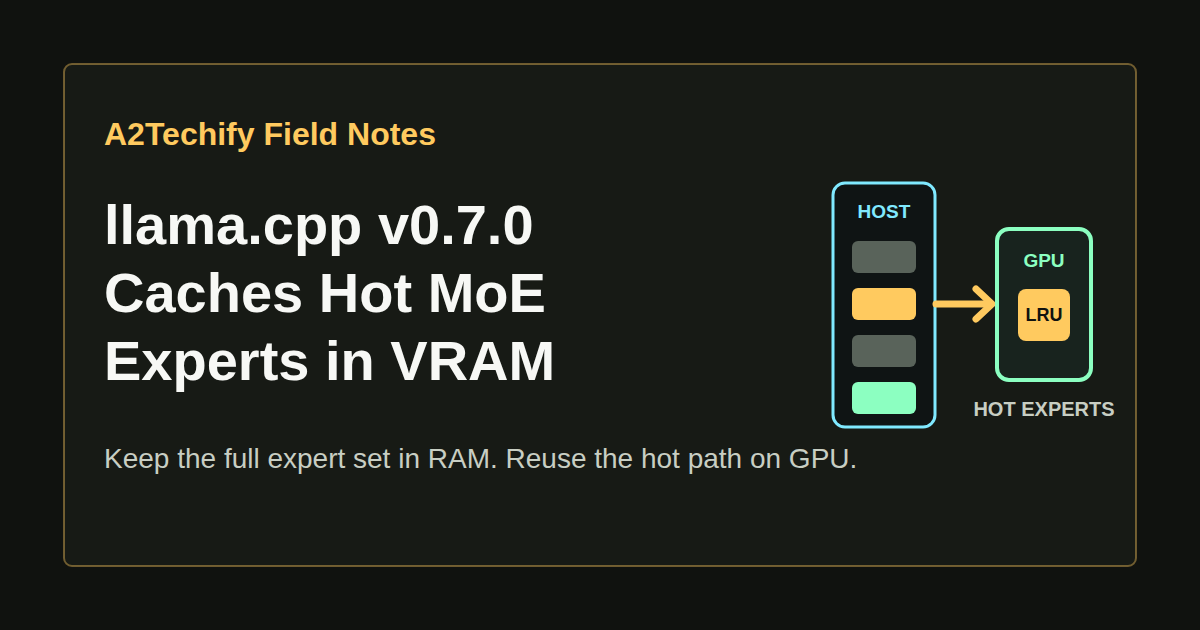
llama.cpp v0.7.0 Adds a GPU Cache for CPU-Offloaded MoE Experts
llama.cpp v0.7.0 can cache frequently used MoE experts on the GPU while keeping the full expert set in system memory.
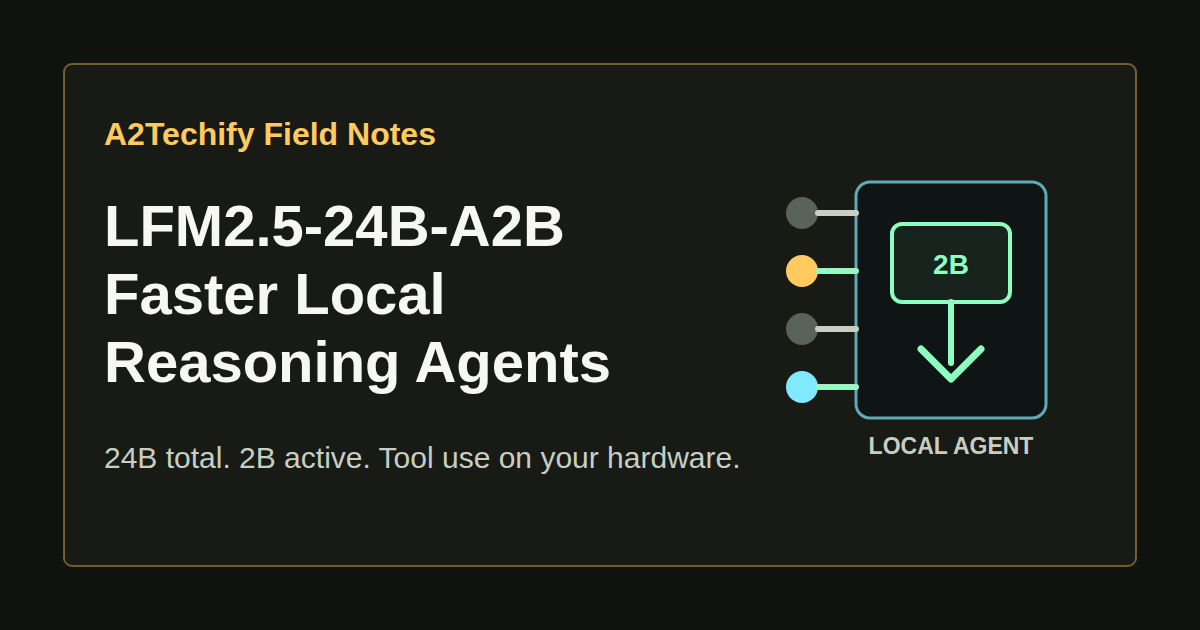
LFM2.5-24B-A2B Brings Faster Reasoning Agents to Local Hardware
Liquid AI's open-weight LFM2.5-24B-A2B activates 2B of its 24B parameters per token, supports tool use, and ships in formats for local agent runtimes.
Transformers Can Now Run GGUF Models Without Leaving Python
Hugging Face is bringing llama.cpp-style GGUF quantized checkpoints into Transformers, starting with fast Apple Silicon inference for Qwen3.5 models.
gpt-oss Turns Open Weights Into Agent Runtime Choices
OpenAI's gpt-oss models make open-weight reasoning practical for agent stacks, but teams still need to treat prompt format, memory, tooling, and safety as runtime contracts.
Muse Glimmer Shows What a Practical Local-Agent Stack Looks Like
How Muse Glimmer, LoRA, QLoRA, and quantization fit together when you build a local agent for real work.