
Research, experiments, and implementation notes filed under hugging-face.
Transformers Can Now Run GGUF Models Without Leaving Python
Hugging Face is bringing llama.cpp-style GGUF quantized checkpoints into Transformers, starting with fast Apple Silicon inference for Qwen3.5 models.
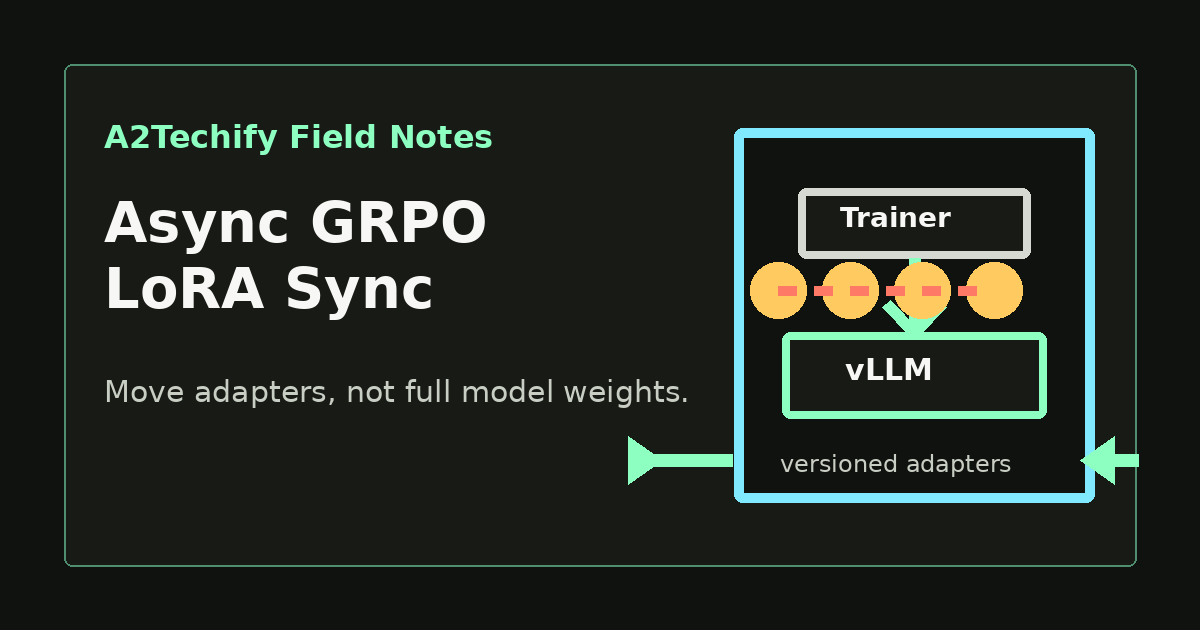
TRL Async GRPO Can Sync LoRA Adapters Instead of Full Weights
TRL v1.14 adds adapter-only vLLM sync for AsyncGRPOTrainer, making distributed RL training less dependent on shared GPUs and full-weight transfers.
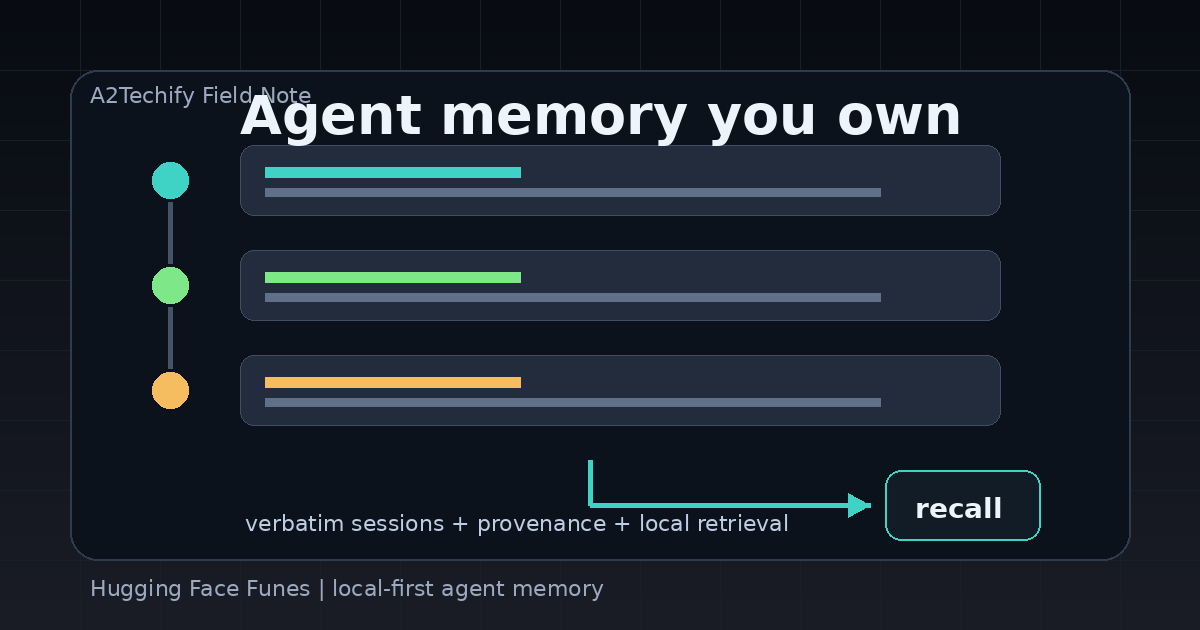
Hugging Face Funes Turns Agent Sessions Into Owned Memory
Hugging Face's funes is a practical local-first memory layer for coding agents: index raw session traces, keep provenance, and share through a dataset only when you choose.
GPU Scheduling Is Becoming AI Infrastructure Work
A practical look at why GPU allocation order matters for AI teams running mixed training, inference, quantization, and batch workloads.
A Workable Artifact Layout for LeRobot Training Runs
Using manifests, checksums, and Hugging Face Storage Buckets to keep mutable robotics runs under control.